I'm pretty confident I personally could pass the Turing Test today in both directions:
1. I could convince someone I am human
2. I could tell AI from a human
I am sure I could do it given an hour of texting, maybe I could get it down to a couple minutes with practice
Is this a novel thing to say in July 2026?
Notes
- deepseek-v4-flash-0731 + pi report add draft comments to val town blog: $0.11 another handful of tasks for 30 min: $0.08 i didn't miss frontier models. on the contrary, being able to read the reasoning, was actually a big upgrade towards intelligence too cheap to meter!
- @rileytomasek i agree it's all about abstraction & interfaces! but that's true at every level of abstraction, so when ai writes 600 lines of slop, that creates bad abstractions and interfaces it was trying to change the semantics of one of our MCP tool calls to be much more complex and hard…
Text may be partial · Read original
- @training_loop Surprisingly, both are a lot dumber than me!
- @rileytomasek I'd be quite shocked to find this didn't matter. That tech debt or bad writing or "confusion" more generally wasn't "expensive" in the long run I feel like this is something us programmers used to have to explain to the MBA types who didn't get the craft, who were so excited…
Text may be partial · Read original
- It seems naive to follow your passion and curiosity and hope the money will follow However I think it works so often because if you do something for intrinsic motivation: 1. It'll be naturally interesting to at least some others. The world is large and people aren't so dissimilar 2. You'll spend more time on it because you like it intrinsically The world surprisingly rewards people who find ways to be their best selves. Not easy!!! But nice to live in such a world when it works out
- @TylerAlterman Think about the productivity of Sept if you crush these Aug goals
- @jasoncrawford @rootsofprogress I feel like @majamediaco or @phokarlsson or @camillericketts would know someone
- @willpienaar What if you test the dumber LLM on their understanding so you can't fake it?
- I feel like this tweet aged well I haven't been able to *viscerally feel* the difference between Claude model releases since Opus 4.5 I've been building a lot with Fable Max and Opus Sol Extra High, and they're constantly making mistakes and poor technical choices For one example, today I asked Opus Sol Extra High to try to repro a bug. It failed. I gave a hint. It got it. I asked it to send a PR of a fix. The diff was 600 lines and super complex. I asked if there was a simpler version. It came up with one after some hints. I asked it to code it. It was 60 lines. I asked if we could reuse existing codebase patterns. The diff was down to 10 lines. I had to nudge it to get lint to pass. I had to nudge it to add a regression test. Sure we could add "skills " about each of these. Tried that. A mountain of skills doesn't equal more intelligence. I don't think it's a skill issue on my part either, but if you think so, I'd love to know about it! For another example, I made a /goal in both of those frontier models to make something faster. Measurable right? Perfect for super smart agents without human in the loop. They both did embarrassly terribly. Constantly coming up with super complex and impractical solutions I'd never use, that also didn't move the needle much. They went down silly rabbit holes and were constantly losing the forest for the trees. They needed lots of guidance and did terribly when I let them go off for a while. With my help we made lots of progress though! Over the past 3 years, LLMs felt like they went from a toy to roughly the skill of a college intern then to a new grad and finally to someone with ~3 years experience, and they've been stuck there for the past 8 months or so. Still such a long way to go to get to "staff engineer"! Maybe we're in some uncanny valley where as they get closer to your own intelligence, the differences become more glaring? I'm BAFFLED by all the people talking about loops, dark factories, and not reading the code. I feel like I finally have a handle on state of the art coding models (July 2026), and the limitations are way far away from being able to code independently without dramatically increasing technical debt. I guess those guys might be alright if newer smarter models can bail them out! All to say, I'm excited for even smarter models than the crazy smart ones we have today. The gradations of human-level intelligence are much more nuance and wide-ranging than we had realized! My current naive thesis on how to make models smarter (free for the taking for any of my friends working on LLMs!) is that the current bottleneck is that LLMs are bad at explainations/writing/legibility and that if you can find some way to make LLMs good at that, you'd be dramatically increasing their intelligence while at the same time increase their worst capabilies: writing and explaining stuff to humans (diifficult skills!) If you cannot explain something simply to someone less smart than you, you don't truly understand it. Why don't we reward LLMs based on how well they can explain/teach dumber LLMs complex things which you can verify via then testing the dumber model post explaination? Maybe this is already a technique folks tried? It's kinda like a twist on CoT, but I think could be more impactful Last LLM improvement idea: I think they need to be trained and runmulti-modally on text. Right now they effectively are listening and speaking. They can't "see" the text on the page and reason visually about it. That was a huge unlock for humans and I imagine would be for models too. They seem to constantly make the sort of errors you'd only make if you weren't looking at the text with your eyes
- i am a sucker for making the pareto fronteir more legible 🤩 https://x.com/cognition/status/2082913381678194927
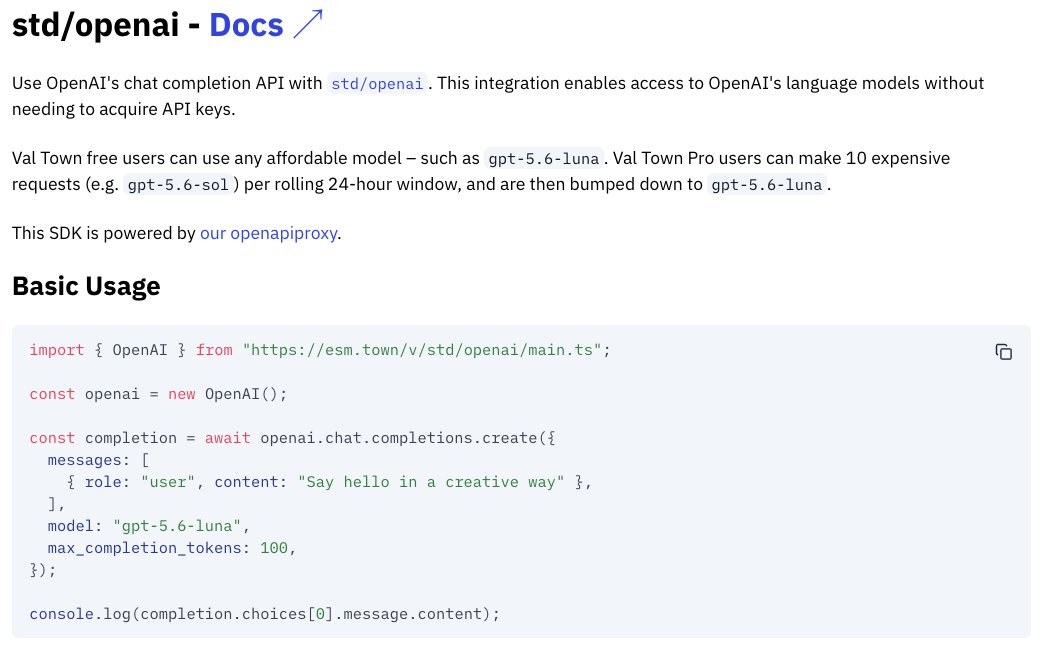
- We at Val Town – for years – have given all our users some free amount of OpenAI inference so you don't have to grab an API key to add just a *bit* of AI to your app This price reduction means that the models we give you and the amount we can afford to give you both goes up! https://x.com/OpenAI/status/2082878156483219672 https://x.com/stevekrouse/status/2082942804246872510/photo/1
- @ankrgyl product when??
- @tanishqk would love to hear how it goes!!
- Has anyone done onboarding evals for agent plugins? In other words, daily automated tests that spin up fresh containers with Claude Code, codex, ask it to install your plugin, authenticate to it, and use it, and report on any frictions it runs into? cc @ankrgyl
- It costs roughly $3B to hold a US national election Or $20 per voter (about 154M Americans voted in 2024) That’s roughly $20 transfer roughly a byte of data So that’s equivalent to $20 billion / GB!!! In other words, it’s roughly 200 BILLION times more expensive than normal home internet data transfer ($0.10/GB)
- In theory, LLMs should be good at judging each other's writing. Shouldn't we be able to train a model to detect slop and another to produce less of it at the same time? I'd imagine the big labs are already doing this? I wonder why the slop problem still exists
- Intelligence remains a huge bottleneck LLMs are smart, and still have a long way to go. Case in point: their writing is slop A lot changes when AI writing becomes indistinguishable from good human writing. I’m not sure what reward signal lets you RL/hill-climb your way there.
- @willemhelmet potluck is @hipotluck
- val town's current growth system architecture most of this is built on val town. including our crm! i'll report back if that was as dumb a decision as it sounds https://x.com/stevekrouse/status/2082489649168052704/photo/1

- @sharanbabu2001 You can only verify something formally specified which most of programming is not
- @sharanbabu2001 Good question! I think this assumes a common, but false premise that we need more clarity up-front Programming is an activity, like writing, where you figure out what you're doing as you do it. Like how I'm writing and rewriting this very tweet! I'm rewriting as I react to my…
Text may be partial · Read original
- i've been thinking about this a lot https://x.com/jeffreyhuber/status/2079708414905860441
- @sharanbabu2001 me too! but counter-intuitively, i wonder how much we'll notice, especially with the given agent paradigm as model speed approaches 1k tok / s, the new bottleneck becomes tool calls i wonder what new llm-coding paradigms we will invent to take advantage of all this speed (and… https://x.com/stevekrouse/status/2082203379665629333/video/1

- @seflless My reactions are faster than the AIs responses to my earlier reactions, so they queue up
- @cooperx86 This is exactly what I'm looking for! Thanks!!
- what does 460 tokens/s feel like? i did some spelunking and i am left with more questions than answers... https://x.com/stevekrouse/status/2082139757874721200/video/1

- @bernhardsson I've spent the last 30 minutes trying to use this API with AIs help and haven't been able to get it up and running. Still trying!
- @joshk @firstround @legibility_bot please add this to the legible asks database First Round has an amazing track record of kickstarting the careers of ambitious and hardworking folks - me included!
- Great article https://davidnicholaswilliams.com/its-not-empowering-to-hand-off-the-details/
- I have a little robot that unlocks my door from the inside (so I don't have to carry a key) The problem was it wouldn't calibrate on my door. It was designed for 90° turns, but my lock only needs 15° In the past, this would've been a showstopper But I asked AI if it could help... At first, it suggested I snoop on the bluetooth connection to figure out the protocol Then it realized that we could probably just decompile the app's SDK and read its source code. That worked! It told me to switch to my mac and run some python for it. Unfortunately, it couldn't run the scripts directly because Claude Code Desktop didn't have bluetooth permissions, but my shell did. Thinking about it now, I probably should've used Claude Code or Codex in the Terminal. Anyways, it took a while, lots of backs and forths, we had some misunderstandings, it was massively overcautious in the beginning, but we finally got the lock calibrated! Feels like magic! I threw the repo up on github in case anyone in the future (ie me) runs into a similar issue – hopefully it can save them some time https://github.com/stevekrouse/switchbot-latch-calibration

- RT @jasoncrawford: In all the sci-fi depictions of AI I know of, I can't think of one in which there are multiple tiers of AI, some smarter…
Reposted by Steve
Text may be partial · Read original
- @Celeris_ai Play with it yourself here https://celeris-coder.val.run/
- The new @Celeris_ai model is fast! I love fast https://x.com/stevekrouse/status/2080822080023441892/video/1

- @GaryMarcus @spicey_lemonade @grok Ha! Good to see you here! It seems to me that all but the robotic chef prediction has been achieved, but I guess it's debatable Could you make your predictions more precisely decidable?
- @spicey_lemonade @GaryMarcus @grok - has gary marcus responded to these failed predictions
- is "steering" just stopping the model, and sending the new message, but it makes you feel less bad about it?
- From a Date Me Directory user: "I appreciate what you're doing with the directory and I think making a Date Me doc really helped me clarify my intentions, even if I met someone elsewhere." Self-legibility is the the first, and often most important, benefit of writing a date-me-doc
- @oanaolt I'll tell my mom
- @JustJake But what about slack connect between custom slacks? We need a protocol!